Meet Canto, our first speech model
By Steven Van ·
Wispr says its in-house Canto model beat Google, OpenAI, AssemblyAI and Deepgram on noisy, real-world dictation tests.
Wispr Flow now runs on Canto, the first speech model the company has built itself. It's rolled out for everyone, with nothing to switch on.
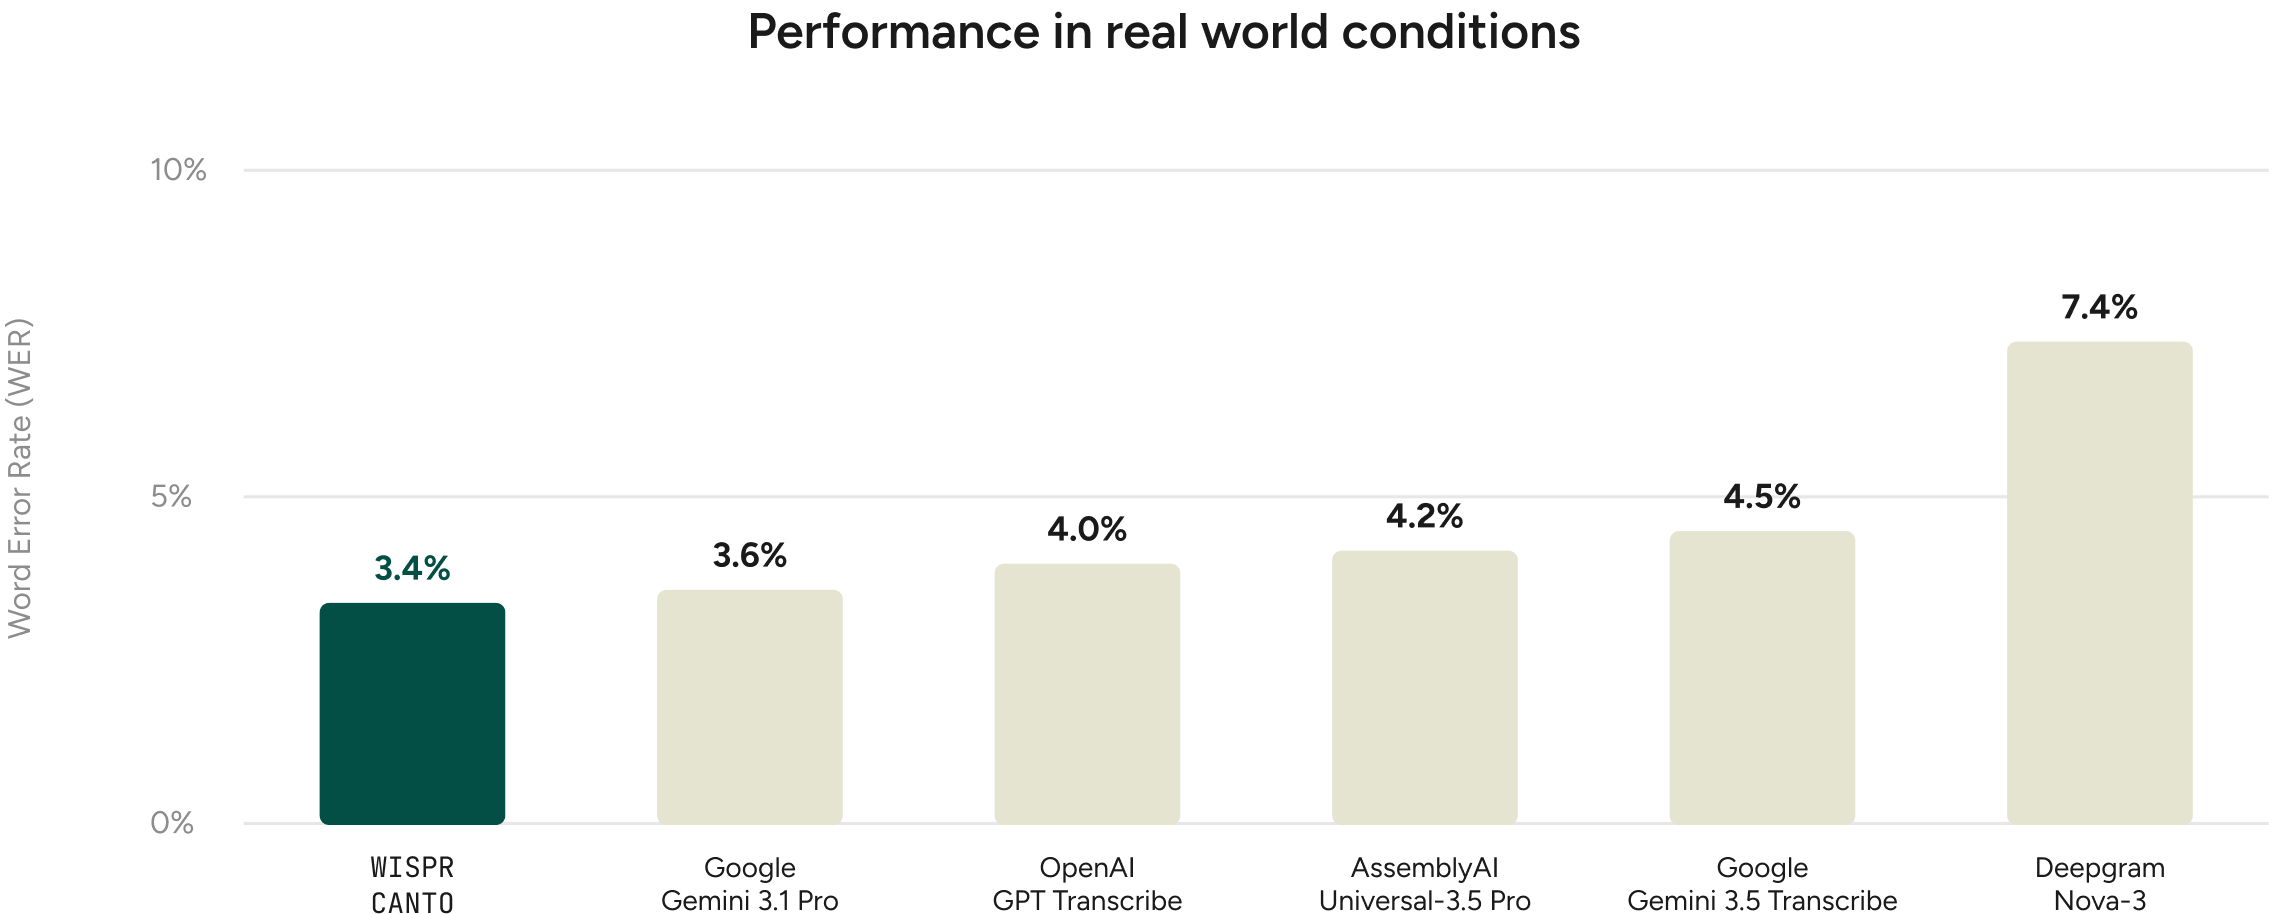
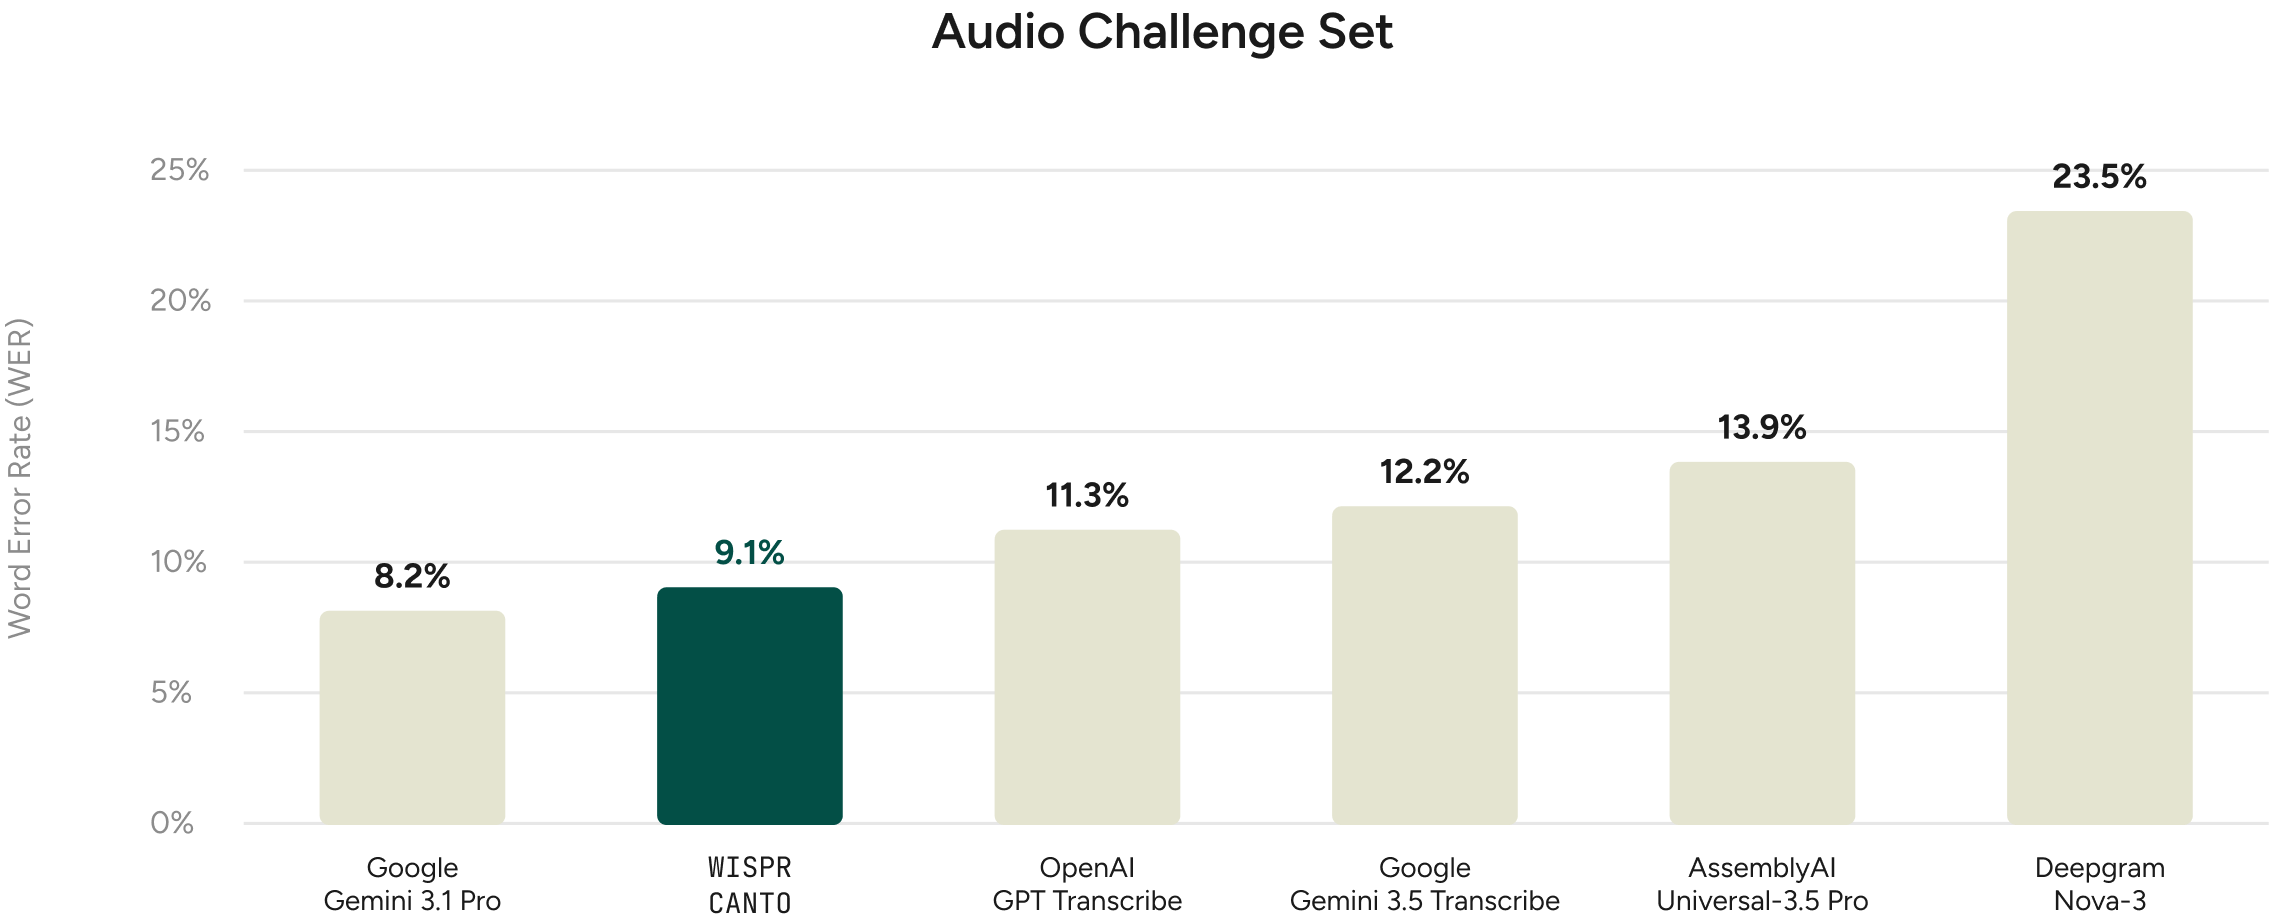
Most speech models are trained and tested on clean audio recorded in quiet rooms with good microphones, which isn't where people actually use Flow: on a train, in an open office, or speaking quietly so as not to disturb anyone. Canto was built and measured against those conditions instead. On an evaluation of 10 hours of real-world English Flow dictations from more than 2,300 speakers, Canto had the lowest word error rate of every model tested, including models from Google, OpenAI, AssemblyAI and Deepgram. On a separate set built to stress-test the hardest audio, with background conversation, music, traffic, wind and whispered speech, Canto was the most accurate of the real-time models tested, ranking second overall behind Gemini 3.1 Pro, a larger multimodal model not suited to real-time use.
Wispr is already training Canto's successor at more than ten times the scale, with better recognition in difficult conditions and broader language coverage planned. Details are in the research post.