ElevenCreative adds Seedance 2.5 for 30-second one-prompt videos
By Steven Van ·
The ByteDance model brings regional edits and up to 50 multimodal references to ElevenLabs' creative suite.
ElevenLabs keeps pushing ElevenCreative beyond audio, and it just added one of the most capable video models available anywhere. Seedance 2.5, the new flagship model from ByteDance, is now live inside the creative suite. You can generate native 30-second videos from a single prompt, reshape any part of the frame with regional edits, and load up to 50 multimodal references into one generation. To underline the point, ElevenLabs says the entire announcement demo was made in one single prompt.
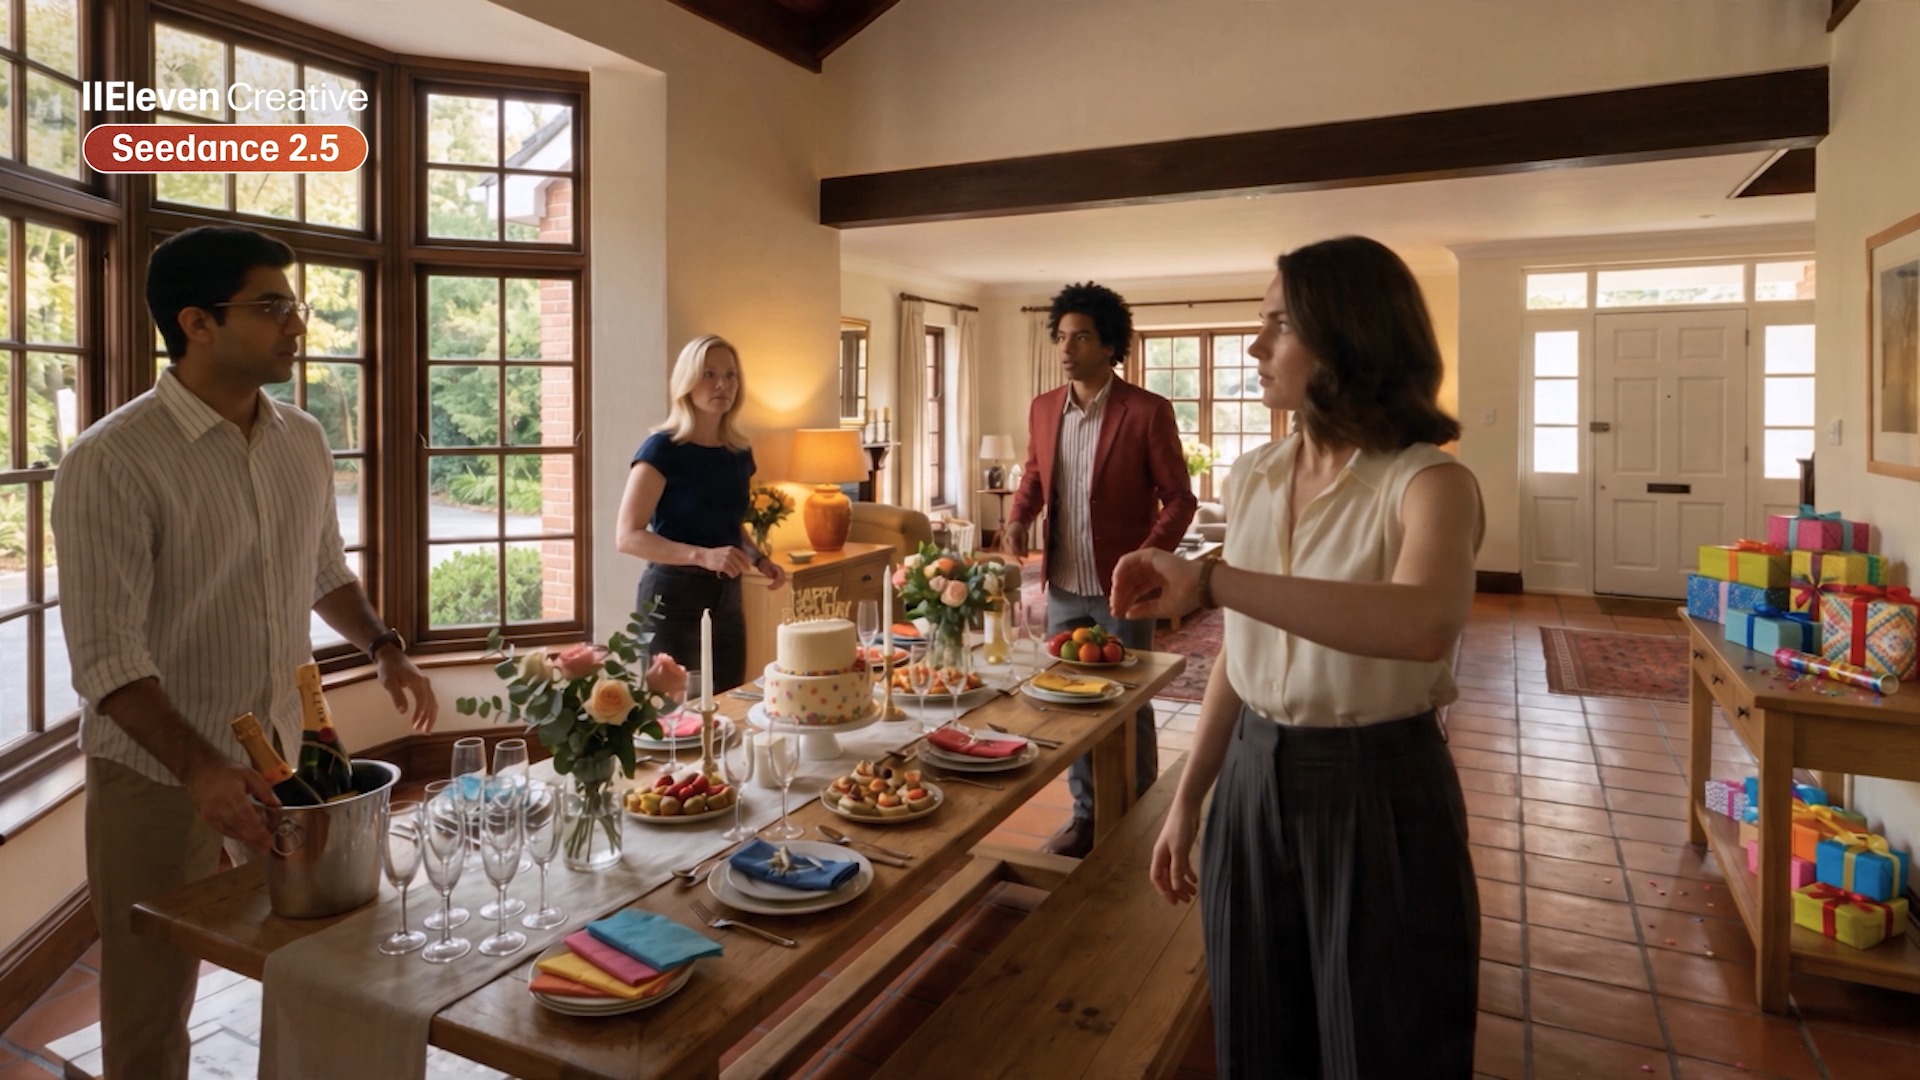
Native 30-second videos, no stitching required
Most AI video tools still cap a single generation somewhere between 5 and 15 seconds, which forces creators to stitch clips together and hope the character, lighting, and motion survive the seams. Seedance 2.5 generates a continuous 30-second video in one pass. That is long enough for a full product spot, a scene with a setup and a payoff, or a social ad that does not feel like three clips taped together. ByteDance also built the model to produce video and audio together in a single pass rather than layering sound on afterward, and generations can be extended over multiple rounds when you need something longer.
Regional edits: fix one corner, keep the shot
The second headline feature is regional editing. Instead of regenerating an entire clip because one element is wrong, you can select a region of the frame and reshape just that part: swap what a character is wearing, clean up a background, change a prop. For anyone doing client work or iterating toward a specific look, this is the difference between a tool you fight and a tool you finish in. A near-perfect generation no longer has to go back in the queue over one detail.
50 references to lock characters, voices, and worlds
Seedance 2.5 accepts up to 50 multimodal references in a single generation. According to ByteDance, that breaks down as up to 30 images, 10 video clips, and 10 audio files. In practice, references are how you get consistency: the same face across every shot, a wardrobe that does not mutate between angles, a location that stays recognizable, a voice that matches. Fifty slots is enough to define a small cast, a set, and a soundtrack direction before the model generates a single frame.
Why this lands well inside ElevenCreative
ElevenCreative already bundles ElevenLabs voice, music, and sound effects models with image and video generation, plus Flows, a node-based canvas for chaining models together and batch-running generations. Dropping Seedance 2.5 into that stack means a creator can go from script to voiced, scored, 30-second video without leaving one workspace. The one-prompt demo is the clearest signal of where ElevenLabs wants this to go: describe the piece once, and let the suite carry it from idea to finished cut. For solo creators and small teams, that collapses what used to be a multi-tool pipeline into a single tab.
Seedance 2.5 is rolling out across several creative platforms this week, but the ElevenCreative version is notable for how tightly it sits next to best-in-class audio. If your videos live or die on voiceover and sound design, this is the integration to try first.