
Anastasios Angelopoulos
Co-founder and CEO
Live rankings of the best text-to-image AI models — compare Flux, DALL-E, Midjourney, Stable Diffusion, and more.
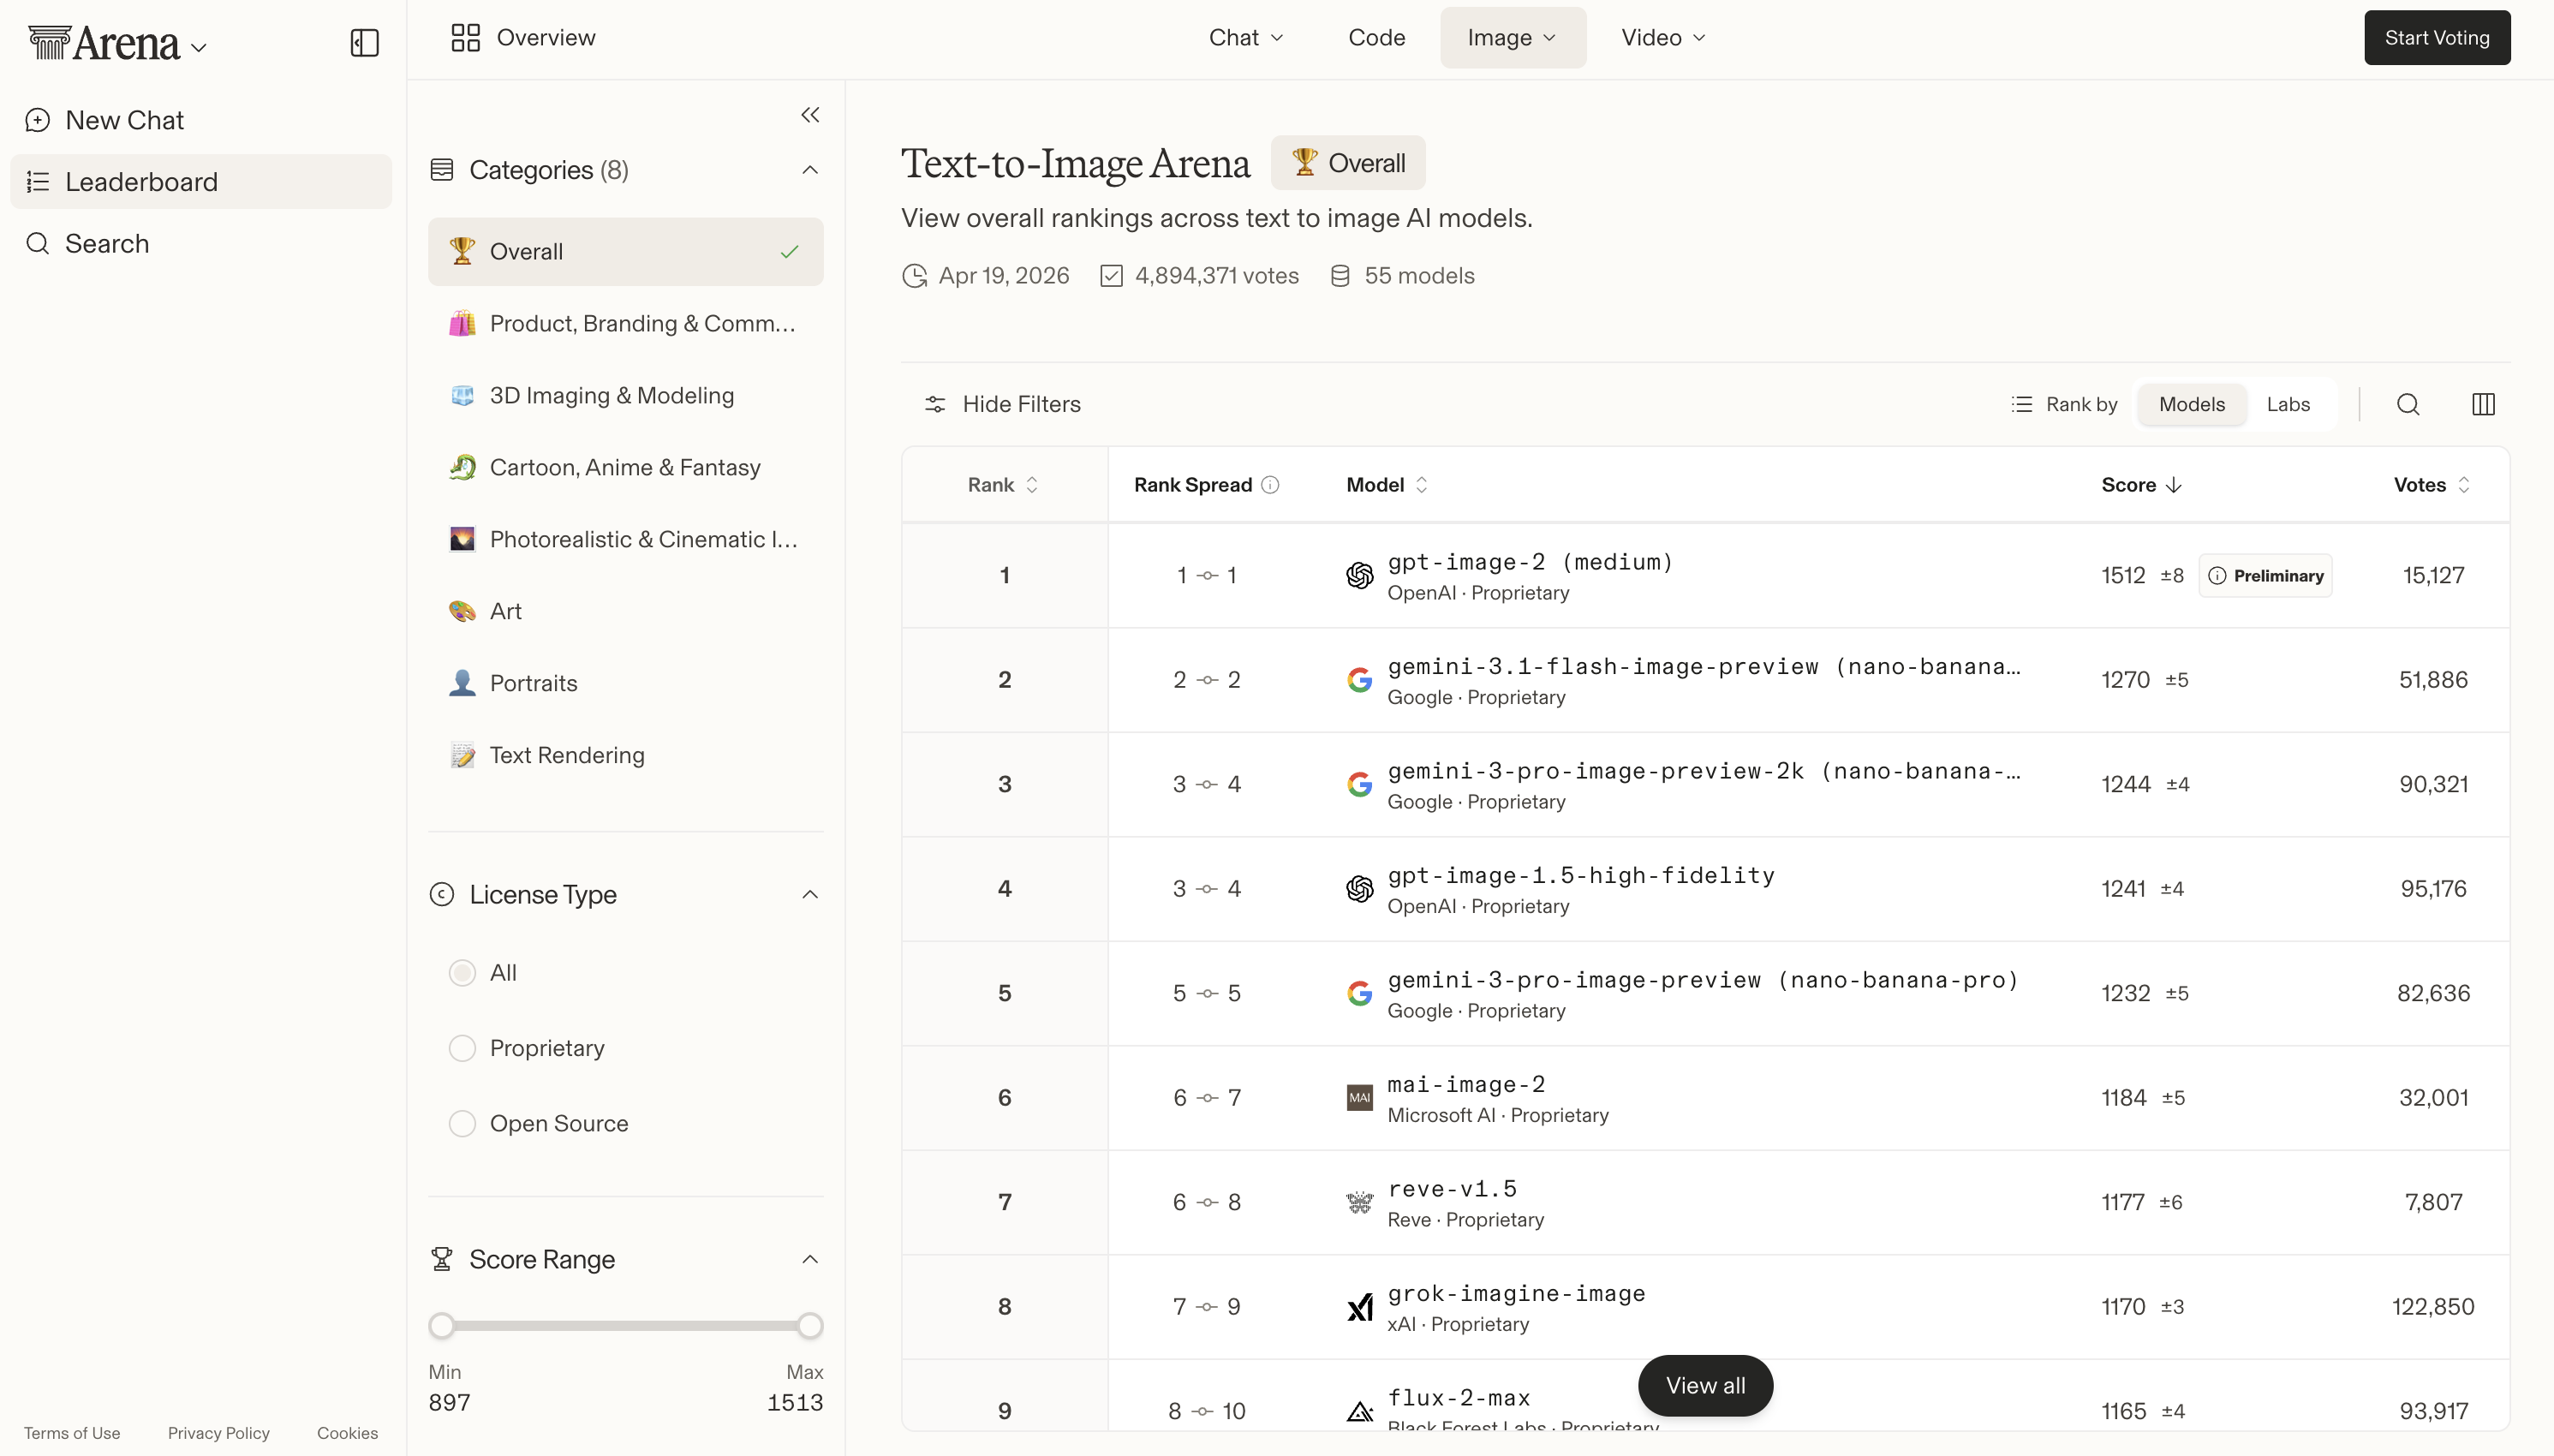
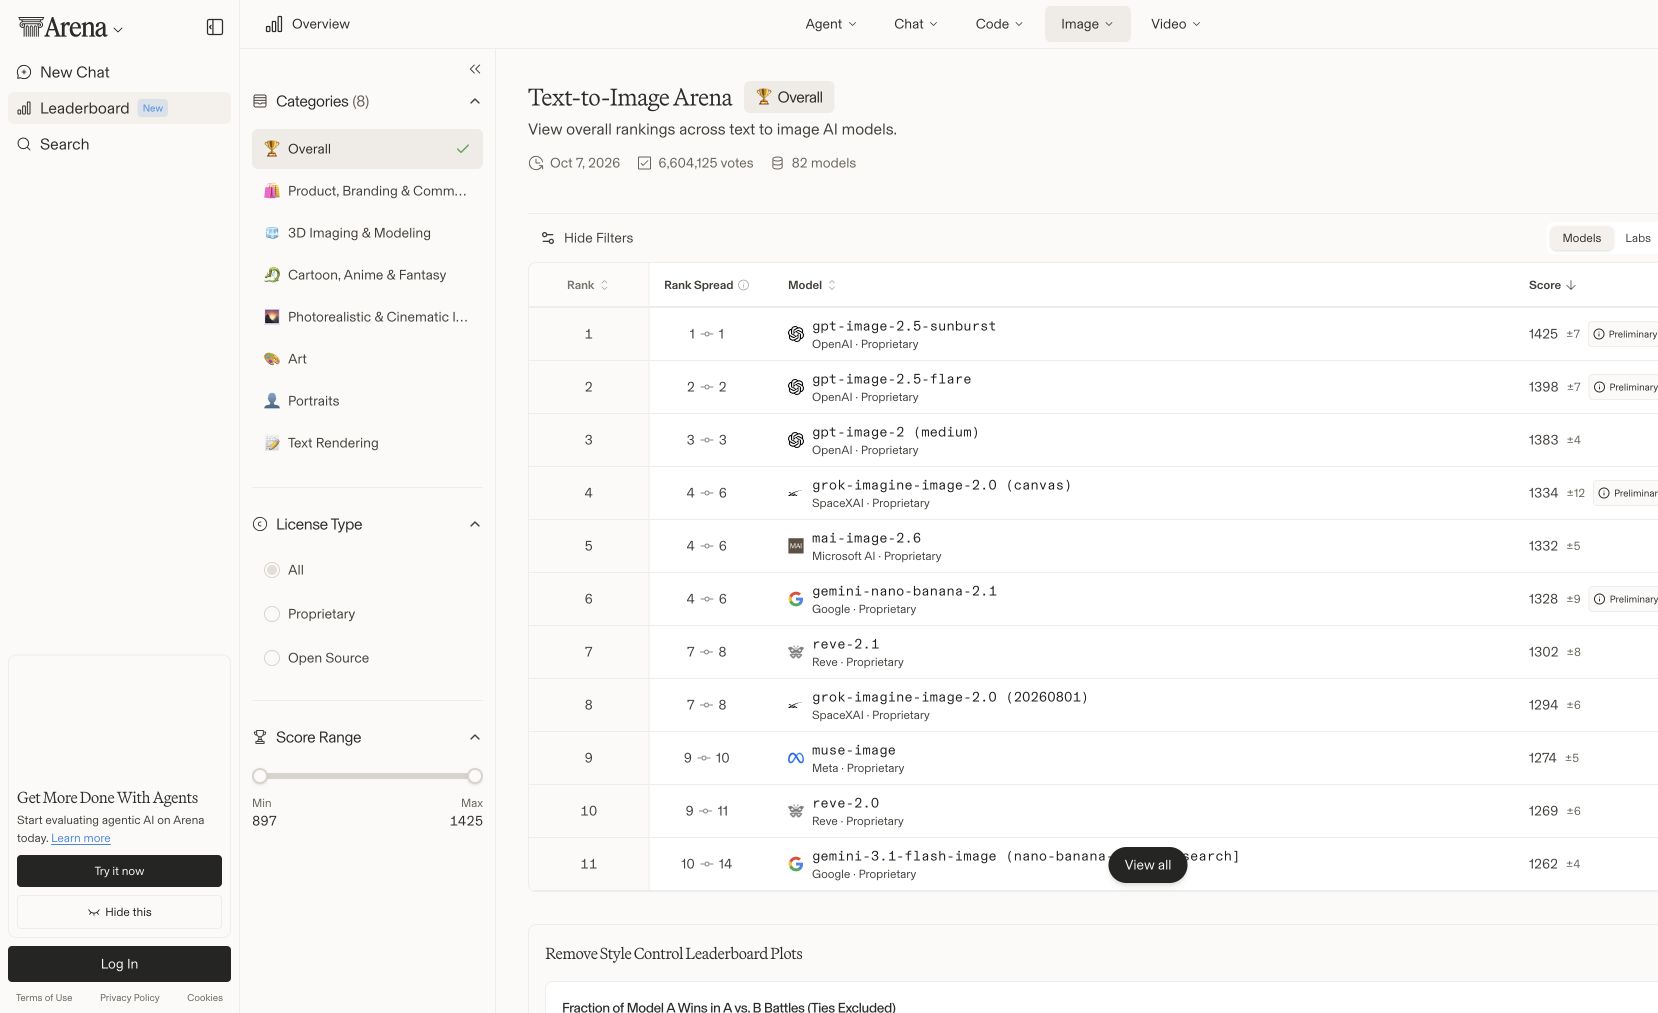
The Arena AI Text-to-Image Leaderboard ranks the best AI image generators based on community votes. Compare outputs from Flux, DALL-E, Midjourney, Stable Diffusion, GPT Image, and more in blind side-by-side tests. See which models lead in quality, prompt adherence, and style.
Common questions about AI Image Generator Leaderboard
Traffic and momentum for AI Image Generator Leaderboard
6 similar picks
Midjourney
AI image generation tool that creates stunning artwork, illustrations, and photorealistic images from text prompts.
Ideogram
AI image generator with best-in-class text rendering — create logos, posters, and visuals with readable text.
OpenRouter
One API for 500+ AI models across 80+ providers — pay with credits that work anywhere, with automatic fallback when a provider goes down.
SVG-Bench
Open human-preference dataset and leaderboard for text-to-SVG generation: 352,270 votes on 14 models across 8 categories.
Arena AI
Chat, compare, and vote for the best AI models — side-by-side battles across 200+ models from OpenAI, Anthropic, Google, Meta, and more.
Similar Launches
SVG-Bench
Open human-preference dataset and leaderboard for text-to-SVG generation: 352,270 votes on 14 models across 8 categories.
Higgsfield for Figma
Generate AI images and video, remove backgrounds, relight, and expand — all inside Figma and FigJam without switching tools.
Recraft for Framer
Framer plugin that lets you create and edit images with AI — generate visuals directly inside your Framer projects.
Higgsfield MCP
Turn Claude into a creative engine — generate professional images and videos with 30+ models directly inside Claude, Cursor, Perplexity, and any MCP-compatible client.
Replicate
Run AI models via API — image, video, audio, and language models from the open-source community, hosted and scalable.
Black Forest Labs
The lab behind FLUX — frontier open and commercial models for image, and now video, audio, and action prediction in one multi-modal architecture.
Comments